 ROS Index
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
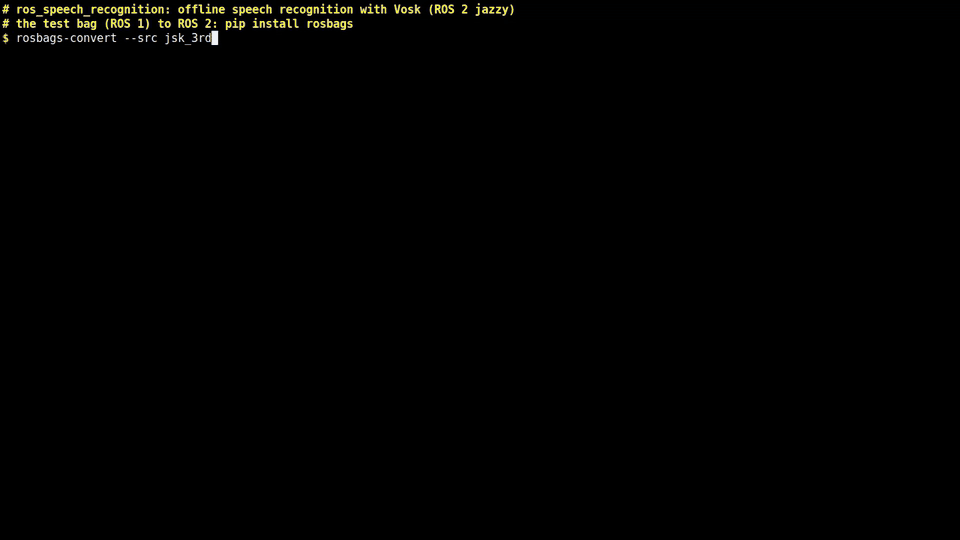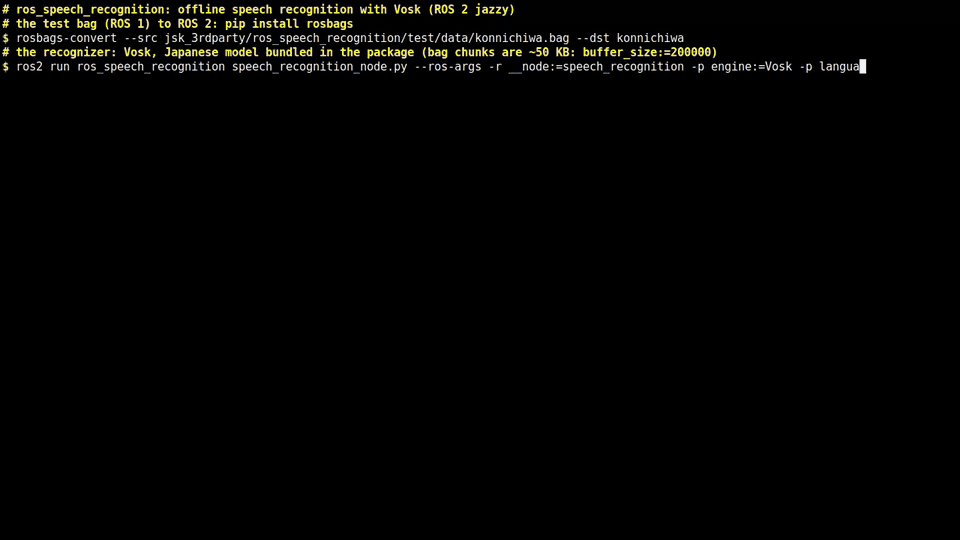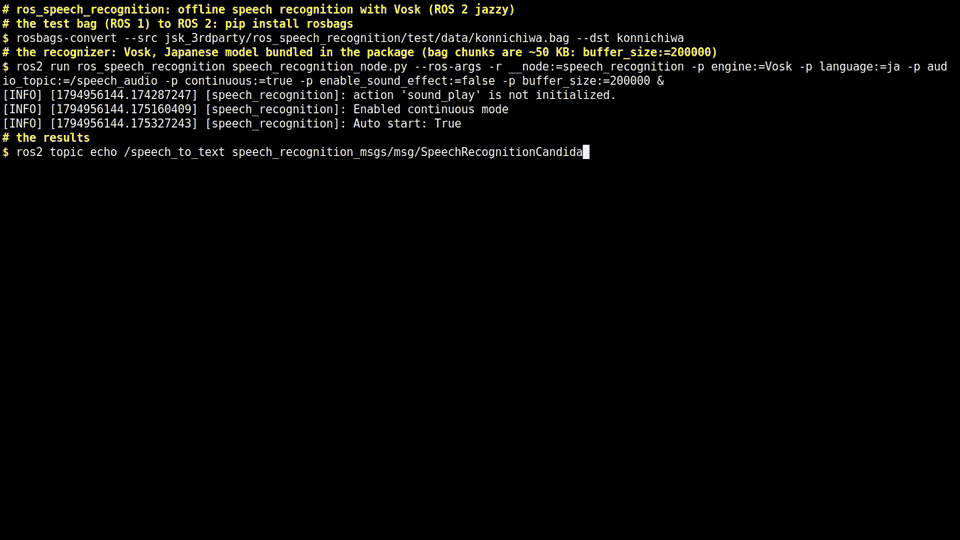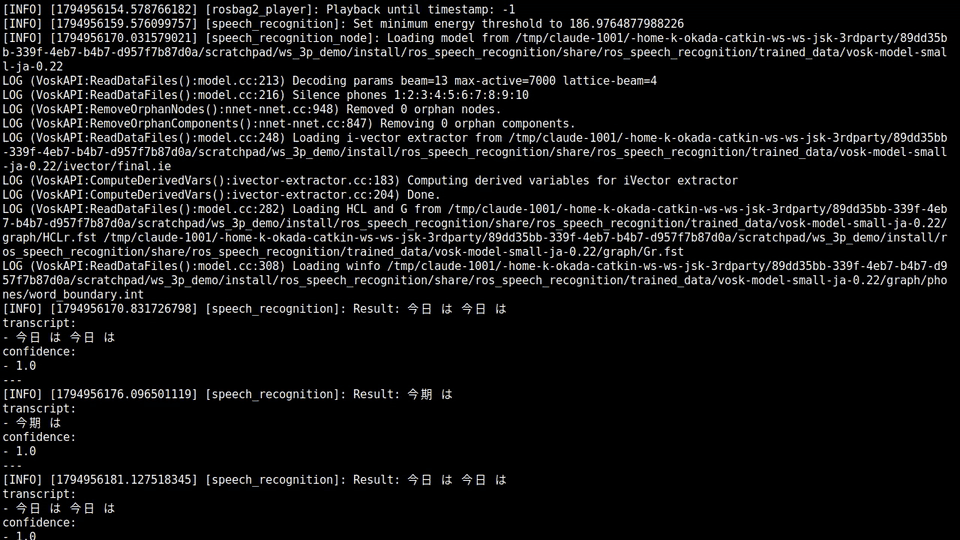
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
| Name | Deps |
|---|---|
| jsk_nao_startup |
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
| Name | Deps |
|---|---|
| jsk_nao_startup |
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]
Messages
Services
Plugins
Recent questions tagged ros_speech_recognition at Robotics Stack Exchange
|
|
ros_speech_recognition package from jsk_3rdparty repovoicevox zdepth chaplus_ros emotion_analyzer gdrive_ros google_chat_ros influxdb_store jsk_power_switching_tools nfc_ros respeaker_ros ros_speech_recognition rospatlite rosping sesame_ros switchbot_ros zdepth_image_transport |
ROS Distro
|
Package Summary
| Version | 3.0.1 |
| License | BSD-3-Clause |
| Build type | CATKIN |
| Use | RECOMMENDED |
Repository Summary
| Checkout URI | https://github.com/jsk-ros-pkg/jsk_3rdparty.git |
| VCS Type | git |
| VCS Version | master |
| Last Updated | 2026-11-18 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Package Description
Additional Links
Maintainers
- Yuki Furuta
Authors
- Yuki Furuta
ros_speech_recognition
A ROS package for speech-to-text. speech_recognition_node.py listens to an audio topic (e.g. from a microphone
through audio_capture), cuts it into phrases by the audio energy, and recognizes them with one of the engines of the
Python package SpeechRecognition: the Google Web Speech API, Google
Cloud Speech-to-Text (also in streaming), the offline Vosk, and others. The result is
published on a topic (continuous mode) or returned by a service. The same nodes and launch arguments work on ROS 1 and
ROS 2.
Requirements
- A microphone (with
audio_capture), or anyaudio_common_msgs/AudioDatatopic. - Per engine (
engine:=...):-
Google(default): internet access; no key is needed (a public key of SpeechRecognition, which may be blocked;~google_keysets an own key). -
GoogleCloud,GoogleCloudStream: a Google Cloud project with the Speech-to-Text API enabled and the JSON key of a service account. Give its path bygoogle_cloud_credentials_json:=/path/to/key.json, or setGOOGLE_APPLICATION_CREDENTIALS. For JSK users, the key is on Google Drive. -
Vosk: offline, no credentials. The small English (vosk-model-small-en-us-0.15) and Japanese (vosk-model-small-ja-0.22) models are downloaded intotrained_data/of the package at build time (ROS 1) or install time (ROS 2) with jsk_data (about 40 MB and 48 MB). -
Sphinx,Wit,Bing,Houndify,IBM: see SpeechRecognition;Bingneeds~bing_key.
-
- SpeechRecognition, vosk and google-cloud-speech are installed into a virtualenv of the package at build time
(ROS 1: catkin_virtualenv with
requirements.txt; ROS 2: uv withpyproject.toml/uv.lock).
Usage
ROS 2
ros2 launch ros_speech_recognition speech_recognition.launch.xml
ros2 topic echo /speech_to_text
# Japanese
ros2 launch ros_speech_recognition speech_recognition.launch.xml language:=ja-JP
# offline with Vosk (language en-US or ja for the bundled models)
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=Vosk language:=ja
# Google Cloud, streaming
ros2 launch ros_speech_recognition speech_recognition.launch.xml engine:=GoogleCloudStream language:=ja-JP \
    google_cloud_credentials_json:=/path/to/key.json
# change an engine parameter at runtime (instead of dynamic_reconfigure)
ros2 param set /speech_recognition language ja-JP
# stop and start the recognition (continuous mode)
ros2 service call /speech_recognition/stop std_srvs/srv/Empty
ros2 service call /speech_recognition/start std_srvs/srv/Empty
Service mode (continuous:=false):
ros2 launch ros_speech_recognition speech_recognition.launch.xml continuous:=false
ros2 service call /speech_recognition speech_recognition_msgs/srv/SpeechRecognition "{duration: 5.0, quiet: false}"
Without a microphone, e.g. with the test bag test/data/konnichiwa.bag (ROS 1; convert it with
rosbags, pip install rosbags). Its audio messages are about 50 KB each, larger
than the default ~buffer_size, which is not an argument of the launch file, so run the node:
rosbags-convert --src test/data/konnichiwa.bag --dst konnichiwa
ros2 run ros_speech_recognition speech_recognition_node.py --ros-args -r __node:=speech_recognition \
    -p engine:=Vosk -p language:=ja -p audio_topic:=/speech_audio -p continuous:=true \
    -p enable_sound_effect:=false -p buffer_size:=200000
ros2 topic echo /speech_to_text speech_recognition_msgs/msg/SpeechRecognitionCandidates
ros2 bag play --loop konnichiwa
Parrot (repeats what it hears with sound_play):
ros2 launch ros_speech_recognition parrotry.launch.xml
ros2 launch ros_speech_recognition parrotry.launch.xml engine:=Vosk language:=ja
ROS 1
roslaunch ros_speech_recognition speech_recognition.launch
rostopic echo /speech_to_text
rosservice call /speech_recognition/stop
rosrun rqt_reconfigure rqt_reconfigure   # engine parameters
# parrot (English: sound_play; ja-JP: aques_talk; use_google:=false: julius_ros)
roslaunch ros_speech_recognition parrotry.launch
roslaunch ros_speech_recognition parrotry.launch language:=ja-JP
ros_speech_recognition.client.SpeechRecognitionClient (ROS 1 only) wraps the service and dynamic_reconfigure:
from ros_speech_recognition.client import SpeechRecognitionClient
client = SpeechRecognitionClient()   # needs continuous:=false
client.language = 'ja-JP'
print(client.recognize(duration=5.0).transcript)
Streaming recognition with Google Cloud (GoogleCloudStream)
File truncated at 100 lines see the full file
Changelog for package ros_speech_recognition
3.0.1 (2026-11-10)
- Merge pull request #583 from k-okada/rosdistro-55247-review rosdistro#55247 review: rename power_switching_tools_ros to jsk_power_switching_tools, fix licenses
- use SPDX license identifiers (BSD-3-Clause, Apache-2.0) in package.xml BSD -> BSD-3-Clause and Apache / "Apache License, Version 2.0" -> Apache-2.0 in all packages (ros/rosdistro#55247 review). The LICENSE files of all of them are BSD 3-Clause and Apache 2.0 respectively. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
- Contributors: Kei Okada
3.0.0 (2026-11-06)
-
Merge pull request #581 from k-okada/ros2-buildfarm-ros-environment Fix ROS2 buildfarm binary jobs: ros_environment, bundled flac, numpy wheel
-
[ros_speech_recognition, respeaker_ros] remove flac binaries bundled with SpeechRecognition from the uv venv The 32bit flac-linux-x86 fails dh_shlibdeps of the buildfarm binary job. SpeechRecognition uses the flac in PATH first, which is an exec_depend. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[voicevox, chaplus_ros, emotion_analyzer, gdrive_ros, google_chat_ros, influxdb_store, power_switching_tools_ros, respeaker_ros, ros_speech_recognition, rospatlite, sesame_ros, switchbot_ros] depend on ros_environment for ROS2 buildfarm The buildfarm builds each package with only its own build dependencies, so without ros_environment $ROS_VERSION is empty and CMakeLists.txt takes the ROS1 branch (same as jsk_common#1835). voicevox also guesses ROS_VERSION from AMENT_PREFIX_PATH when it is unset. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
Merge pull request #580 from k-okada/ros2-google-cloud-stream [ros_speech_recognition] add GoogleCloudStream engine (ROS1/ROS2, rebase of #572)
-
[ros_speech_recognition] use google-cloud-speech for GoogleCloud engine The GoogleCloud engine used google-api-python-client and oauth2client, which are not declared as dependencies. When they are installed in the venv, oauth2client imports the system pyOpenSSL, which does not work with the cryptography installed by google-auth (AttributeError: module 'lib' has no attribute 'GEN_EMAIL'). Send the request with google-cloud-speech, already a dependency of the GoogleCloudStream engine. The config is still built as the REST JSON dict, so user_config (e.g. diarizationConfig) works as before, and show_all returns the same JSON dict. google-api-python-client is kept for python < 3.7, where google-cloud-speech is not available. Also send preferred_phrases as speechContexts (speechContext is not a field of RecognitionConfig), and remove a debug print.
-
[ros_speech_recognition] report GoogleCloudStream stream errors instead of ignoring them Errors of the gRPC stream were swallowed by [except Exception: pass]{.title-ref}, so an invalid credential or a disabled API looked like nothing was recognized.
- errors that reconnecting cannot fix (Unauthenticated, PermissionDenied, InvalidArgument, NotFound) are logged once with logerr and stop the streaming loop, instead of reconnecting on every audio chunk
- other errors (305s session limit, network) are logged with logwarn and the stream reconnects as before
- streams closed by stop_stream() (e.g. self cancellation) are not logged
-
[ros_speech_recognition] import numpy only for GoogleCloudStream engine python3 venv on kinetic/melodic can not see python-numpy (python2), and the engine is not available there anyway. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] add google-cloud-speech and numpy dependencies google-cloud-speech requires python >= 3.7, so skip it on kinetic/melodic python3 venv with a pip environment marker, and add it to pyproject.toml/uv.lock for ROS2. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
[ros_speech_recognition] support GoogleCloudStream engine on both ROS1 and ROS2 use ros_compat instead of rospy, import GoogleCloudStreamingRecognizer only when the engine is selected (google-cloud-speech is not available on python2), add GoogleCloudStream to cfg/ros2 and utf-8 coding header. Co-Authored-By: Claude Opus 5.5 <<noreply@anthropic.com>>
-
add speech_recognition samples using GoogleCloudStream for README.md (#13)
-
[ros_speech_recognition] log interim transcripts for GoogleCloudStream
-
[ros_speech_recognition] add GoogleCloudStream engine for streaming recognition Wrap google-cloud-speech v1 StreamingRecognize so the node can emit interim transcripts on ~voice_interim_topic while still publishing the finalised utterance on ~voice_topic.
File truncated at 100 lines see the full file
Package Dependencies
System Dependencies
Dependant Packages
Launch files
- launch/parrotry.launch
-
- use_google [default: true]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- launch/speech_recognition.launch
-
- launch_sound_play [default: true] — Launch sound_play node to speak
- launch_audio_capture [default: true] — Launch audio_capture node to publish audio topic from microphone
- audio_topic [default: /audio] — Name of audio topic captured from microphone
- voice_topic [default: /speech_to_text] — Name of text topic of recognized speech
- n_channel [default: 1] — Number of channels of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- depth [default: 16] — Bit depth of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- sample_rate [default: 16000] — Frame rate of audio topic and microphone. '$ pactl list short sinks' to check your hardware
- device [default: ] — Card and device number of microphone (e.g. hw:0,0). you can check card number and device number by '$ arecord -l', then uses hw:[card number],[device number]
- engine [default: Google] — Speech to text engine. TTS engine, Google, GoogleCloud, Sphinx, Wit, Bing Houndify, IBM
- language [default: en-US] — Speech to text language. For Japanese, set ja-JP.
- continuous [default: true] — If false, /speech_recognition service is published. If true, /speech_to_text topic is published.
- auto_start [default: true] — Whether speech_recognition starts automatically or not. This parameter works when continuous is true
- energy_threshold [default: 300.0] — Minimum audio energy to consider for recording speech. Raise it if noise is taken for speech, lower it if quiet speech is missed
- dynamic_energy_threshold [default: true] — Raise energy_threshold automatically to follow the background noise. Set false to keep energy_threshold fixed, e.g. when the noise lifts it above normal speech
- self_cancellation [default: true] — Do not recognize the audio when robot is speaking or not.
- tts_tolerance [default: 1.0] — Tolerance second for recognizing whether robot is speaking or not
- tts_action_names [default: ['sound_play']] — tts action name. these servers outputs are ignored by sound_recognition
- google_cloud_credentials_json [default: ] — credentials for google cloud
- launch/parrotry.launch.xml
- ROS2 version of parrotry.launch (based on Michi-Tsubaki's ROS2 port of this package). julius_ros and aques_talk (use_google:=false and ja-JP in parrotry.launch) have no ROS2 port, so the speech engine is given by engine and the voice comes from sound_play.
-
- engine [default: Google]
- language [default: en-US]
- confidence_threshold [default: 0.8]
- tts_action_name [default: sound_play]
- launch/speech_recognition.launch.xml
- ROS2 version of speech_recognition.launch (based on Michi-Tsubaki's ROS2 port of this package)
-
- launch_sound_play [default: true]
- launch_audio_capture [default: true]
- audio_topic [default: /audio]
- voice_topic [default: /speech_to_text]
- n_channel [default: 1]
- depth [default: 16]
- sample_rate [default: 16000]
- device [default: ]
- engine [default: Google]
- language [default: en-US]
- continuous [default: true]
- auto_start [default: true]
- energy_threshold [default: 300.0]
- dynamic_energy_threshold [default: true]
- self_cancellation [default: true]
- tts_tolerance [default: 1.0]
- tts_action_names [default: ['sound_play']]
- google_cloud_credentials_json [default: ]