 ROS Index
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README

**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
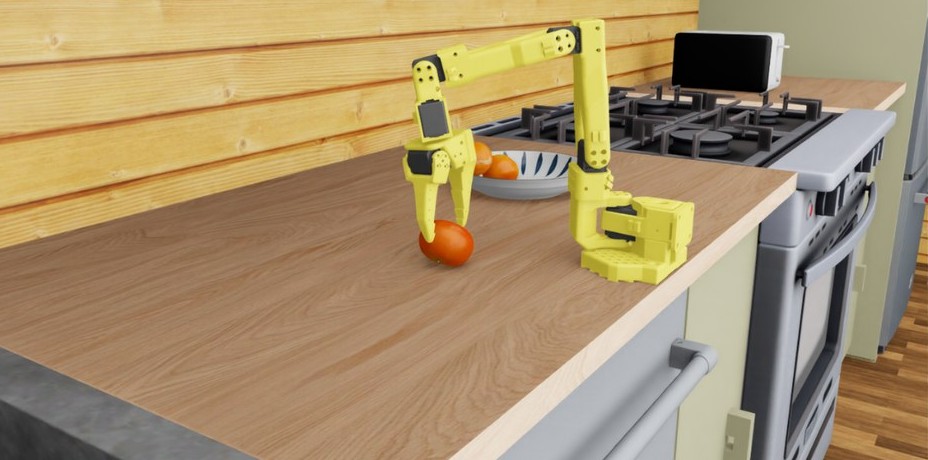
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph

In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file
CONTRIBUTING
Repository Summary
| Checkout URI | https://github.com/automatika-robotics/ros-agents.git |
| VCS Type | git |
| VCS Version | main |
| Last Updated | 2026-10-21 |
| Dev Status | DEVELOPED |
| Released | RELEASED |
| Contributing |
Help Wanted (-)
Good First Issues (-) Pull Requests to Review (-) |
Packages
| Name | Version |
|---|---|
| automatika_embodied_agents | 0.8.0 |
README
**The production-grade framework for deploying Physical AI** [](LICENSE) [](https://emos.automatikarobotics.com/getting-started/installation.html) [](https://discord.gg/B9ZU6qjzND) [**Documentation**](https://emos.automatikarobotics.com) · [**Developer Docs**](https://automatika-robotics.github.io/embodied-agents/) · [**Recipes**](https://emos.automatikarobotics.com/recipes/overview.html) · [**Discord**](https://discord.gg/B9ZU6qjzND)
An SO-101 arm picks oranges in Isaac Sim with a GR00T N1.7 policy, run by the VLA component. An event stops the policy when a VLM watching the camera judges the task done (recipe).
EmbodiedAgents is the intelligence and manipulation layer of EMOS, the Embodied Operating System. An agent is a graph of components, written in one Python file called a recipe: models that see, listen, speak, remember, plan and act, connected by ROS 2 topics and events. Every component is a managed ROS 2 lifecycle node, and the graph can reconfigure itself while it runs.
Components
| Area | Components |
|---|---|
| Language and vision | LLM and VLM answer, call tools, describe and ground what the camera sees, and keep a turn-based chat history. SemanticRouter sends each query to the right component, by meaning, by an LLM or by a decision model. |
| Decisions | DecisionComponent asks a decision model typed questions (yes or no, a choice, a score) and publishes each answer with its probabilities, for events to act on. |
| Perception | Vision detects and tracks objects, and lifts its 2D boxes to metric 3D boxes on depth. MotionDetector finds motion in images or point clouds, ignoring the robot’s own. |
| Speech | SpeechToText, with voice activity detection and a wake word, and TextToSpeech. |
| Manipulation | MoveIt plans collision-free motion, picks and places through MoveIt 2, around the objects the cameras see. VLA runs vision-language-action policies served by LeRobot, such as GR00T, π0.5, SmolVLA and ACT. |
| Memory | Memory keeps a spatio-temporal graph of what the robot saw, where and when (eMEM), with tools to search it. |
| Planning | Cortex plans a task in plain language, with every action in the recipe as a tool, and runs the plan as monitored routines. |
Key Features
- Agents that adapt on the fly. Any component can react to what another one publishes. Let a person walking into view wake up your VLM, or let a decision model call time on a VLA the moment the job is done. If the cloud goes down mid-task, the agent switches to a local model and carries on.
- Classical and learned manipulation. MoveIt plans around what Vision lifts into 3D, and VLA runs learned policies. A decision model or a VLM watching the camera can end a policy’s task the moment it is done.
- Run fully offline. Built-in local models for LLM, VLM, detection, speech-to-text and text-to-speech (llama.cpp, ONNX Runtime and sherpa-onnx), with no server. Suited to edge devices and NVIDIA Jetson.
- Any model server. Ollama, OpenAI-compatible APIs (vLLM, SGLang, llama.cpp, LMDeploy), RoboML and the LeRobot policy server, with Chroma for vector search.
- Planning when you need it. Hand Cortex a task in plain language and it builds a plan from everything your recipe can already do, calling on any component along the way. Each plan runs as a routine you can pause or abort from the web UI.
A Recipe Is a Graph
In this recipe, speech reaches a VLM that answers out loud and tells the memory what it sees. Vision’s 3D boxes become MoveIt’s planning scene, and a decision model watching the camera ends a VLA task through an event. Cortex can join a graph like this one and plan with every component’s actions as its tools, including those of other packages such as Kompass for navigation.
Quick Start
A VLM agent that answers questions about what its camera sees:
from agents.clients.ollama import OllamaClient
from agents.components import VLM
from agents.models import OllamaModel
from agents.ros import Topic, Launcher

text0 = Topic(name="text0", msg_type="String")
image0 = Topic(name="image_raw", msg_type="Image")
text1 = Topic(name="text1", msg_type="String")

qwen_vl = OllamaModel(name="qwen_vl", checkpoint="qwen2.5vl:latest")
qwen_client = OllamaClient(qwen_vl)

vlm = VLM(
    inputs=[text0, image0],
    outputs=[text1],
    model_client=qwen_client,
    trigger=text0,
    component_name="vqa"
)

launcher = Launcher()
launcher.add_pkg(components=[vlm])
launcher.bringup()
Components are wired with topics and events. Here a detector runs on every frame with a small local model, and the VLM describes the scene only when a person appears:
```python from agents.components import Vision from agents.config import VisionConfig from agents.ros import Event, FixedInput
detections = Topic(name=”detections”, msg_type=”Detections”)
File truncated at 100 lines see the full file